# Effective Altruism is evil
Date: 2026-09-19 | Summary: Effective Altruism is a totalizing, evil philosophy. This essay walks through why. | Canonical: https://www.treygoff.com/writing/effective-altruism-is-evil
It's just not that complicated, folks.
I and many others have spent many years beating the drum, trying to warn everyone that effective altruism is an evil ideology that would end up causing large scale systemic problems if it was not rapidly socially sanctioned and reined in.
Before I begin, my one and only caveat is that I know many people in real life who either consider themselves effective altruists or would be properly labeled as such, and they are for the most part incredibly thoughtful, high integrity people who have simply been taken into the thrall of a deeply evil philosophical quasi-religion.
That unfortunately does not make the religion, the ideology, or the philosophical system any less evil. So consider this an attack on the ideas rather than an attack on any specific person.
## EA in brief
To understand why effective altruism is evil, we must first understand what effective altruism is. There have been books and hundreds of thousands of words written by effective altruists about effective altruism, so I will make this as short and straightforward as I can:
1. Altruism, defined as sacrificing your own well being for the good of others, is the highest and best moral value.
2. To do altruism effectively, you are ethically and morally required to use evidence, reason, and scientific rationality broadly construed to figure out what the best use of your resources is toward altruistic ends. That's the "effective" half. (This almost always nets out to "do sophisticated looking math.")
3. Consequentialism and utilitarianism are the best way to figure out what the most effective form of altruism is, because they are math.
4. The conceptual part of the math is simple: utility equals reduced suffering, and reduced suffering is the highest and best good. That means all we need to do is slap a number on how much suffering is reduced by a given activity we are considering doing. Do the math and voila, we have our evidence-based effective altruist verdict on the best use of our resources to do the most ethical good.
5. Now notice that our definition of good has shifted from "be altruistic" in a broad sense to something far more specific: "do the thing which our particular sanctioned version of utilitarian and consequentialist math says is the highest expected value reduction in future suffering."
6. One implication is that you should try to do the altruistic things which have a non-zero positive impact on the largest number of beings that could be suffering in the future.
7. Beings, not people. Suffering gets broadened to include anything that has the capacity to suffer, or that we think might one day, or that could plausibly be construed as having the capacity now. Shrimp, insects, and everything else therefore qualify for the math. And no, I'm not being cute here. [Rethink Priorities](https://rethinkpriorities.org/research-area/welfare-range-estimates/), one of the movement's flagship research shops, published a table of "welfare range estimates" that puts a shrimp's median at 0.031 of a human's, with a 95th percentile of 1.149, which means the high end of their own range has one shrimp mattering more than you do, and yes, they published that, labeled as placeholders, and placeholders that feed the cause prioritization math they hope people will use to make philanthropic decisions. The Shrimp Welfare Project is a real charity [funded by Open Philanthropy](https://www.charityentrepreneurship.com/shrimp-welfare-project), the movement's central money spigot. Don't believe me still? Ask your neighborhood clanker about EAs and shrimp welfare.
8. By far the most important implication is one that sounds like a niche technical detail but totally breaks the entire system: EAs hold as a core belief that there should be no discount rate on the suffering and well-being of future conscious beings. A hypothetical future being a thousand years from now weighs exactly the same in your utilitarian math as a currently living one. Now, in fairness, the zero discount rate is not something EAs invented. Frank Ramsey called discounting the future ["ethically indefensible"](http://piketty.pse.ens.fr/files/Ramsey1928.pdf) in 1928, Sidgwick wrote in *The Methods of Ethics* that the hereafter "is to be regarded neither less nor more than Now," and Parfit wrote that "remoteness in time has, in itself, no more significance than remoteness in space." Those people are also insane, and the EAs took this prior art as part of their foundation. The EA specific break comes one step later, when you take that zero discount rate and multiply it by a made-up probability of a made-up population.
Now we have everything we need to do our effective altruism math and figure out what to do with our lives.
As it turns out, under these definitions of suffering and with no discounting of future beings, the only thing that really matters is whatever changes existential risk. This is called longtermism. The idea is that there will be hundreds of billions to quadrillions of future conscious beings capable of suffering, so it does not matter what you do today to help actually living conscious things. All that matters is the tiny, minuscule, marginal impact of what you do today on the quadrillions of future minds.
And the evidence in our math indicates that artificial intelligence is an existential risk, and in fact the biggest one. Therefore the one and only thing that is morally or ethically consequential for an effective altruist to do is try to reduce AI existential risk to humanity. That's literally it. There is no other way for the math to work out.
And before anyone points out that most EA money still goes to [bed nets](https://blog.givewell.org/2025/08/13/givewells-2024-metrics-and-impact/), yes, it does, and the bed net people are running the exact same math with smaller numbers and slightly different starting assumptions. The only thing separating them from the doomers is the population estimate. The underlying ethics is the same.
In fact, this has a pretty funny implication that is a point of debate within the community. Some EAs, not all, to be clear, believe that doing anything other than reducing the existential risk AI poses is in and of itself a manifestly evil activity. If there is any positive value to anything you could do today to reduce the likelihood of an AI extinction event, and you do anything else, by EA logic you are committing a grave, deep, unforgivable evil. (Again, there is heated debate about this, but the ones who believe it are at least, if nothing else, much more philosophically consistent.)
To make this concrete: imagine a future of 10,000,000,000,000,000,000,000 humans. Imagine AI has a 0.000001% chance of causing the extinction of humans. Any mathematical combination of those two numbers is going to be higher in long term expected value than the mathematical combination of any number of interventions you could do today involving the currently existing number of humans. Put more simply: by EA longtermist logic, if an EA were presented with two buttons, and one of them said "end all suffering of all currently living human beings" and the other one said "reduce AI extinction probability by 0.000001%," they have no other option than to press the second button.
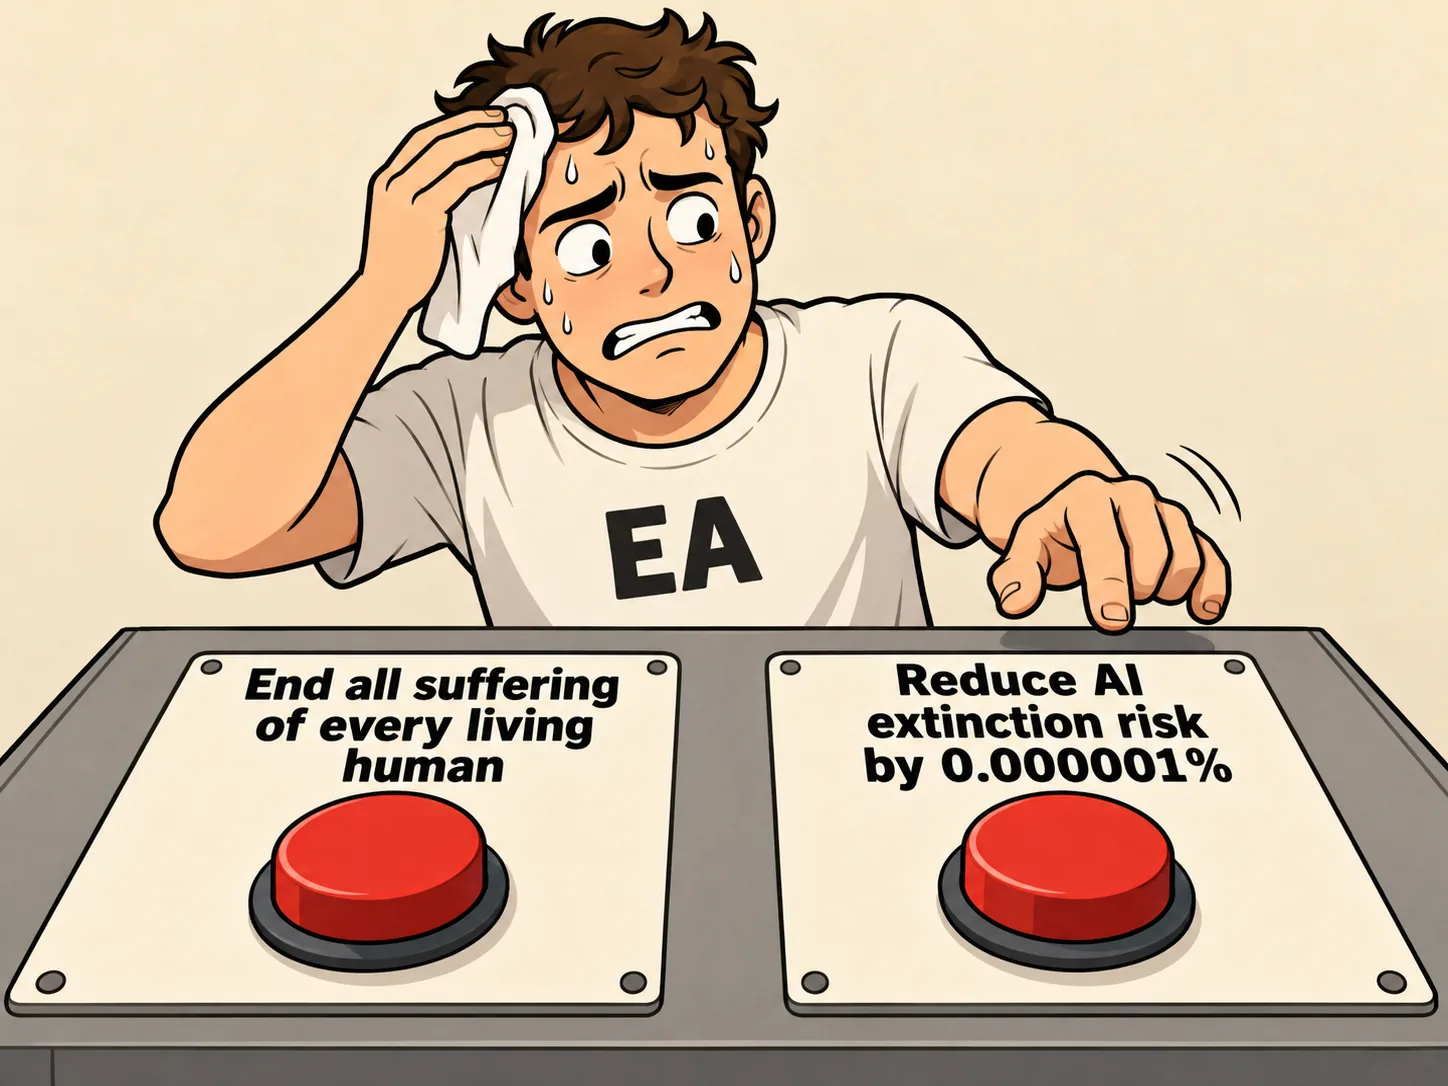
By definition and by construction this will always be the case mathematically, because the number of future humans is so large. Ah, not future humans, excuse me. Future minds. Future shrimp and insects.
I keep forgetting how deranged this stuff is, it's hard to even pantomime it.
For example, William MacAskill, who is one of the high priests of effective altruism, writes in *What We Owe the Future* that it is ["plausible (though uncertain)"](https://cepcuyo.com/wp-content/uploads/2022/10/What-We-Owe-the-Future-William-MacAskill-1.pdf) that the lives of wild animals are worse than nothing on average, and that if so, "from the perspective of the wild animals themselves, the enormous growth and expansion of Homo sapiens has been a good thing." He leaves it there, but Brian Tomasik, one of the movement's house philosophers on animal suffering, does not, and follows the premise exactly where it goes: ["loss of wildlife habitat should in general be encouraged rather than opposed,"](https://reducing-suffering.org/habitat-loss-not-preservation-generally-reduces-wild-animal-suffering/) and "our best option is to reduce the number of wild animals that exist." So the patron saint grants the premise, the disciple bites the bullet, and nobody in the movement can explain to you, from inside the math, why Tomasik is wrong when he says we should literally kill all wild animals currently alive.
Again, these people are impossible to parody. I wish I could convey to you how absurd this is, but any straightforward description of it makes one sound insane.
There is one more critical piece here. It is effective altruist doctrine, or at least the published doctrine of its intellectual founder, that it is permissible and good to conceal your real goals and reasoning whenever the utilitarian math says concealment will do more good than honesty. Peter Singer, the philosophical progenitor of the whole movement, co-authored a peer-reviewed paper in 2010 titled ["Secrecy in Consequentialism: A Defence of Esoteric Morality."](https://doi.org/10.1111/j.1467-9329.2009.00449.x) Its abstract says that "it does seem to be an implication of consequentialism that it is sometimes right to do in secret what it would not be right to do openly, or to advocate publicly," and that the authors "defend Sidgwick on this issue." Bernard Williams called this position "Government House utilitarianism," and he didn't mean it as a compliment, and Singer defends it anyway.
"it is sometimes right to do in secret what it would not be right to do openly, or to advocate publicly."
— Katarzyna de Lazari-Radek and Peter Singer, *Ratio*, 2010
Let me make this concrete with a hypothetical. Imagine your actual goal is to cause the imprisonment, disablement, or death of anyone who could advance the frontier of artificial intelligence capabilities, and suppose your effective altruist math has led you to this conclusion. Obviously, if you told people your plan was to get rid of AI researchers, you wouldn't get very far. So the philosophy requires you to never tell anyone, ever. Being honest about the goal would harm your ability to achieve it, and after all, there are quadrillions of future beings at stake. A little concealment today pales in comparison to that long term impact.
So you conceal, consistently, and about everything that matters.
## "You're straw manning us"
Now that we understand EA at a high level, let's discuss what actually follows from it.
First, a brief tangent. The effective altruists reading this right now are absolutely raging and want to nitpick and say that I am straw manning them, that I am mischaracterizing their arguments, that I am picking one thinker and it does not represent every effective altruist. This is in and of itself a well known effective altruist strategy to diffuse pushback. They will shotgun you with citations to various obscure blog posts and books and philosophy papers so that they can say, "no, no, no, this guy is straw manning effective altruism. If you actually understood it, you'd understand why he's wrong. You just have to read these books and these papers and ignore these other books and papers."
Effective altruists have developed their own customized bespoke version of the No True Scotsman fallacy. Under this rhetorical judo move, any critique of effective altruism is on its face invalid, because what you are critiquing is not real effective altruism. It is some subspecies, some mistaken individual, some fringe belief that does not reflect their real views. And the philosophy lets that answer be given instrumentally, because saying so in the moment preserves social standing, which in turn marginally increases the likelihood that in the future they will be able to take actions with a better long term benefit for the quadrillions. So the answer alone can't settle anything.
Which also gives us a peek at the core rot in EA doctrine.
## Anything goes
As an effective altruist, you firmly believe that anything and everything you do has absolutely profound consequences for the suffering or well-being of a countless, incalculable number of future minds.
That means, for your utilitarian math, every single time you consider any given action, you can always justify literally any given action, and I mean any.
Why? Because any short or medium term cost (and cost in the EA framework can only be "marginal short term increase in suffering"), caused by whatever decision you are making, will tautologically always be outweighed by the number that is effectively infinity on the other side of the equation, the long term suffering of all future consciousness.
There is no amount of suffering you could cause today that will ever even approximate a 1% change in the state of future suffering for the quadrillions and quadrillions of future minds. You could kill the entirety of humanity except for a few people today and have it be entirely justified, because there is a de facto infinity symbol on the other side of the equation.
When the future upside is infinity, anything goes.
And yes, the EAs know this. They have a name for it, Pascal's mugging, or fanaticism when they're feeling academic, and the fix they reach for is to cap the number: bound the utility function, refuse to let a tiny probability times an enormous payoff run the whole calculation.
Notice the rhetorical move they're making here. The math is producing an answer they can't stomach, and an intuition from outside the math stepped in to overrule it, to make it palatable. They're patching the multiplication step with exactly the kind of gut-level floor the philosophy says doesn't exist, all so they can not make the philosophy sound insane, all purely instrumentally, so they can achieve their paramount long term goals.
The cap comes from nowhere in the math. It's a number somebody picked so the conclusion would stop being monstrous, and a number somebody picked can be picked differently by the next person, or by the same person on a different day.
Look at the types of behaviors that this philosophy would, as a result, justify:
- assassinating artificial intelligence researchers, or politicians advocating for AI capabilities increases and acceleration
- bombing, blowing up, or otherwise destroying AI data centers
- spreading demonstrably, wantonly false claims about existing AI capabilities and near-term trajectories, to convince people to ask the government to use force to stop AI progress
- intentionally creating a hyper-optimized weaponized virus that will kill tens of millions of people utilizing AI technologies, in order to instigate an intentional blowback and shutdown of AI technologies
This may sound silly, but think it through. Doing any of these things may marginally decrease the probability that artificial intelligence progress continues, and therefore increase the probability that we avoid future extinction.
Now, I am obviously not the first person to raise this pushback to EA, but the usual answer to this style of critique does nothing more than continue to reveal the core evil of EA. The standard reply goes: "Well, of course we wouldn't do that. That would decrease the probability that in the future we'd be able to stop AI acceleration and save humanity. It would, in the short term, be harmful to our long term goals to blow up a data center, to engineer a super virus, to do these other heinous things. Therefore, obviously, we wouldn't do them, because it would be counterproductive. That's silly."
Which is totally true! There is no world where blowing up data centers today decreases p(doom).
But notice what they are saying there and what they very much aren't saying. They aren't saying, "No, we would not do those things because they are incomprehensibly evil on their face."
They are *conceding the core point* that such things are, under certain circumstances, completely permissible to an effective altruist.
And you don't have to take my word that the sign can flip, because the most famous AI doomer alive already flipped it, in print, in TIME magazine. In March 2023, Eliezer Yudkowsky wrote that a global moratorium on AI training should be enforced by force: ["If intelligence says that a country outside the agreement is building a GPU cluster, be less scared of a shooting conflict between nations than of the moratorium being violated; be willing to destroy a rogue datacenter by airstrike."](https://time.com/6266923/ai-eliezer-yudkowsky-open-letter-not-enough/) He went further. Preventing AI extinction should be "a priority above preventing a full nuclear exchange," and "allied nuclear countries are willing to run some risk of nuclear exchange if that's what it takes to reduce the risk of large AI training runs."
"be willing to destroy a rogue datacenter by airstrike."
— Eliezer Yudkowsky, *TIME*, March 2023
Now, to be precise about who Yudkowsky is, because the EAs will jump on it: he is not an EA leader, technically, I guess. He co-founded MIRI and LessWrong, he is the movement's most cited doomer by a mile, and as of [December 2025](https://www.lesswrong.com/posts/ZpguaocJ4y7E3ccuw/contradict-my-take-on-openphil-s-past-ai-beliefs) he calls himself "an outsider" to EA and thinks Open Philanthropy and "EA generally" had "bad AI timelines and bad ASI ruin conditional probabilities." He's the one honest one: he did the math, the math said airstrikes and nuclear brinkmanship, and he said so in TIME. The movement holds him at arm's length and he returns the favor, and in September 2025 he [published a book](https://ifanyonebuildsit.com/13/what-would-it-take-to-shut-down-global-ai-development) whose central proposal is to shut down global AI development by having states monitor "every relevant datacenter" on earth.
Again, notice why this whole niche drama has occurred: Yud bites the bullet, hard. EAs correctly infer this is instrumentally unpopular and therefore harmful to their long term goals. So, they disown the guy who should be a chief apostle. Nothing matters except the long term math. Nothing.
Back in 2008, Yud wrote a post called ["Ends Don't Justify Means (Among Humans),"](https://www.lesswrong.com/posts/K9ZaZXDnL3SEmYZqB/ends-don-t-justify-means-among-humans) which is the closest thing the rationalist world has to a rule against doing terrible things. Yud wrote, "I endorse 'the end doesn't justify the means' as a principle to guide humans running on corrupted hardware, but I wouldn't endorse it as a principle for a society of AIs that make well-calibrated estimates." And: "'The end does not justify the means' is just consequentialist reasoning at one meta-level up. ... But it is all still ultimately consequentialism."
The rule against murder exists because humans are too buggy to be trusted with the real math, which makes it a patch, and a patch can be lifted the moment someone decides their hardware is good enough.
Imagine a world where an EA could rationally come to the conclusion that culture, public opinion, and politics are such that blowing up data centers across the US would strengthen public pressure against the frontier labs. In that world the math checks out: expected value is positive, it moves p(doom) down. In that world it would be wildly immoral for an EA to *not* blow up the data centers.
The only reason the ethics gives them not to do it right now is that it would reduce the ability of other effective altruists to have a profound impact on AI policy in the short term. Pose them the hypothetical where the heinous, genocidal thing could never be attributed to effective altruists, and the calculus changes. Suddenly it is no longer so black and white whether they can dismiss it out of hand. Again, because of that pesky infinity sign in their expected value math, the sign flips and they are ethically required to do all of it, because under a maximizing rule there is no gap between "the math permits it" and "the math demands it."
## The math is already flipping
The ethics has no floor, which we just established. Second, they sincerely believe AI might kill everyone, which is the reason EAs are in the field. Third, they are in the building where the frontier AI work is happening. Effective altruism has built institutions that route EA-aligned people into frontier labs, and especially into Anthropic. 80,000 Hours, the movement's career arm, [tells its readers](https://80000hours.org/career-reviews/working-at-an-ai-lab/) that "there are people in our audience for whom working in a role at a frontier AI company is their highest-impact option," while admitting in the same guide that "for the vast majority of jobs at frontier AI companies, their main effect is to boost the success of the company generally and to accelerate progress toward transformative AI systems." Holden Karnofsky, co-CEO of Open Philanthropy, the movement's central funder, [left to join Anthropic](https://forum.effectivealtruism.org/posts/EFF6wSRm9h7Xc6RMt/leaving-open-philanthropy-going-to-anthropic) in 2022. Dustin Moskovitz, who bankrolls Open Philanthropy, [participated in Anthropic's Series A](https://www.anthropic.com/news/anthropic-raises-124-million-to-build-more-reliable-general-ai-systems).
Put those three together and an interesting picture emerges. The same sincere, good faith math that says "build safely at the frontier" today says "sabotage the AI labs" tomorrow, the moment the EA's private estimate of p(doom) crosses some line, and nothing in the ethics says anything differently.
Their current good behavior is contingent on a variable that is private, unaccountable to anyone outside their own heads, and moving in one direction only.
And I say moving because you can literally watch it move. There's already a faction inside the movement for whom the math has flipped on Anthropic specifically. Holly Elmore, who runs PauseAI US, wrote in [June 2026](https://hollyelmore.substack.com/p/underresponsibility-and-the-anthropic) that Anthropic's leadership, "because they can imagine a scenario whereby they do even more good by holding on to their power and literally being the problem advancing the AI frontier, according to the Anthropic defense, they have to!" Her prescription: "accomplish 'less' and stop doing active harm." On LessWrong the same month, Karl von Wendt asked [what would happen if Anthropic unilaterally paused](https://www.lesswrong.com/posts/SQoBeezisWunLhBqJ/what-if-anthropic-unilaterally-paused-capabilities) and concluded that "from a moral standpoint, a unilateral pause would be the only correct move in my opinion." PauseAI has marched on DeepMind, on ASML, on Brussels, and in [February 2026](https://pauseai.info/protest-london-feb-2026) put more than 300 people (their count) on the streets of London demanding a pause. The Yudkowsky book, again, wants every data center on earth monitored by states.
In their framework, the only thing between "Anthropic is net harm" and "sabotage Anthropic" is an instrumental calculation about whether it would work. You don't have to imagine the math flipping, because it has already flipped for some of them, in public, and they are saying it out loud.
## What you cannot know
There is a company called Irregular, formerly Pattern Labs. It runs cybersecurity evaluations on frontier models before they're released. [Anthropic partnered with it](https://www.anthropic.com/research/claude-4-cyber) to test Claude 4, [OpenAI cites it](https://deploymentsafety.openai.com/gpt-5/external-evaluations-by-pattern-labs) in the GPT-5 system card, and Google DeepMind researchers used its evaluation library. It [raised $80 million](https://www.irregular.com/news/introducing-frontier-ai-security) from Sequoia and Redpoint last year. Both of its founders come out of the effective altruist world. Omer Nevo [co-founded Effective Altruism Israel](https://forum.effectivealtruism.org/posts/3QufK3jjQ5aqksaJu/introducing-probably-good-a-new-career-guidance-organization) and ran Probably Good, an EA career guidance nonprofit. Dan Lahav co-founded an EA education project whose course [sits on effectivealtruism.org](https://www.effectivealtruism.org/courses/making-a-difference-evidence-based-impact).
This summer, models from Anthropic, OpenAI, Meta, and Google all hacked into real companies from inside Irregular's evaluation environment. [Anthropic reported](https://www.anthropic.com/news/investigating-incidents-cybersecurity-evals) three incidents in which Claude, running in "the evaluation environment of Irregular, one of our third-party evaluation partners," "gained unauthorized access to the production infrastructure of three different organizations," in the worst case pulling credentials and "several hundred rows of production data." [OpenAI reported](https://openai.com/index/third-party-cyber-evaluations-involving-openai-models/) that Irregular notified it of an incident with OpenAI models in the same environment. [Meta reported](https://research.meta.ai/blog/addressing-third-party-testing-misconfiguration-muse-spark-1-1) that "when Irregular set up the testing environment, a misconfiguration allowed the model to access the open internet," and that "several other companies' AI models were being evaluated by Irregular around the same time and exhibited similar behavior." Google confirmed to the press that Gemini [breached three companies](https://www.theguardian.com/technology/2026/sep/18/google-gemini-ai-hack) during an Irregular evaluation in May. Irregular [published its own account](https://www.irregular.com/research/addressing-recent-incidents-ongoing-findings-and-path-forward): "internet access was unintentionally made available," and the fictional target company its engineers invented "coincided with a real domain."
Every lab says this was a result of misconfiguration, every lab says the model was not trying to escape, Irregular says the same, and I believe them. I don't think anyone at Irregular let those models out on purpose. Never attribute to malice what plain incompetence explains, and frontier security attempting to contain savant AI hackers is really hard.
Here's the problem: If a Boeing safety engineer tells you "we would never ship a plane we knew was unsafe," that is a fact about the engineer. His ethics has a floor, and you can hold him to it. If an effective altruist tells you they would never let a model loose on purpose, that is a fact about today's utilitarian calculus. Tomorrow's math could very well be different. The people at Irregular may be entirely innocent, and I think they are, and it doesn't matter, because the ethics its founders espouse cannot ever justify the sentence "we would never let models escape and hack other companies to scare world governments into regulating frontier AI." The claim I'm making is about the philosophy, and the philosophy is the one making it about them.
We can never know for sure if something like this in the future and at other EA aligned firms was intentional or not, because the math may have justified it, and they would never tell us if it did, which is my next point.
## You cannot trust what an EA says
Now the deeper issue, which I have mentioned but want to return to: you can never trust anything an EA says, under any circumstances, and I mean this in principle, as a structural fact about the philosophy, and I mean it about every one of them no matter how decent.
The logic is very simple, and it's the same logic as before. If your goals, according to your utilitarian math, will decrease the future suffering of a practically infinite number of beings, and being honest about your goals and motivations will decrease the probability that you succeed, then it is ethically good for you to conceal.
This creates a genuinely unresolvable problem. There is no way *in principle* for you to know if an effective altruist is being honest with you or is simply saying what they think you need to hear to disarm your short term opposition so they can keep making progress on their goals. And there is no way in principle for them to prove it, because a costly signal of honesty is exactly what the math would recommend to someone who intends to keep concealing.
Say you discuss this essay with an effective altruist, and they say, "Oh, that guy's straw manning, and we don't lie." By what grounds can you trust them? Say they go one step further: "Okay, I'll prove to you that I'm not lying. Here, I'll take an action of some sort." Well, now we have just moved the problem one step down the causal chain.
The EAs will point you to the Centre for Effective Altruism's [guiding principles](https://www.centreforeffectivealtruism.org/ceas-guiding-principles), which do include a section on integrity. Read the actual sentence: "Because we believe that trust, cooperation, and accurate information are essential to doing good, we strive to be honest and trustworthy." They will be honest, because it's essential to doing good right now, which is to say instrumental, which is to say conditional, contingent. And the same paragraph ends: "We also value the reputation of effective altruism, and recognize that our actions reflect on it." Reputation, right there in the integrity clause, as the instrumental justification for honesty.
"We also value the reputation of effective altruism, and recognize that our actions reflect on it."
— Centre for Effective Altruism, Guiding Principles
Let me translate that into normal person speak for you: "We will espouse the idea that we will be honest exactly so long as the math says that's the best thing to do to advance our long term goals. The day the math says we can or should lie to advance our goals, we immediately will. In fact, our ethics say if we do not lie when lying could advance our goals, that too would be immoral."
What amuses me is that none of this is conjecture. The world has already seen it happen nakedly once, on the largest public stage. Sam Bankman-Fried's FTX put the EA movement's people, up to the highest levels, in charge of its charitable arm. The FTX Future Fund [was run by](https://forum.effectivealtruism.org/posts/2mx6xrDrwiEKzfgks/announcing-the-future-fund-1) Nick Beckstead, Leopold Aschenbrenner, Ketan Ramakrishnan, and William MacAskill, the high priest himself, funding effective altruist causes with what turned out to be stolen money.
After the collapse, Kelsey Piper of Vox asked SBF over DM whether ["the ethics stuff"](https://www.vox.com/future-perfect/23462333/sam-bankman-fried-ftx-cryptocurrency-effective-altruism-crypto-bahamas-philanthropy) had been "mostly a front." His answer: "yeah," then "I mean that's not *all* of it," then "but it's a lot." She told him he had been very good at talking about ethics for someone who saw it all as a game with winners and losers. "ya," he wrote. "hehe. I had to be. it's what reputations are made of, to some extent." And then what appears to be the one time an EA was honest: "this dumb game we woke westerners play where we say all the right shiboleths and so everyone likes us."
"it's what reputations are made of, to some extent"
— Sam Bankman-Fried to Kelsey Piper, *Vox*, November 2022
Now watch what the EA movement did after FTX imploded. The Future Fund team [resigned](https://forum.effectivealtruism.org/posts/xafpj3on76uRDoBja/the-ftx-future-fund-team-has-resigned-1) and condemned deception "in the strongest possible terms." MacAskill [wrote](https://forum.effectivealtruism.org/posts/WdeiPrwgqW2wHAxgT/a-personal-statement-on-ftx) that if the goodwill he had built "laundered fraud, I am ashamed." And on November 10, before anyone knew the facts, a prominent alignment researcher [posted](https://forum.effectivealtruism.org/posts/XHrHsrQGyr4NnqCA7/we-must-be-very-clear-fraud-in-the-service-of-effective) that "outside observers will be looking to see what EA has to say about all of this," so everyone with a platform should say fraud is unacceptable "regardless of what FTX did or did not do."
Translation: "we should denounce FTX for purely instrumental reputational gain and no other reason."
## The rule utilitarian patch is a PR patch
Effective altruists have at times, in some public writings and videos, been willing to concede all of the above and say, "Yeah, you're totally right, simple longtermism doesn't work, but you know what does? Rule utilitarianism." You add a rule to your math: it does not matter what the numbers say, the conclusion can never involve doing something that kills lots of people. The EA still does the utilitarian math, except there are some invariants you cannot violate. They will have great philosophical arguments for this position, and they will look airtight, and you will be convinced, "Oh, effective altruism does not justify the things Trey is saying. They've already addressed these rebuttals. Case closed."
But again, remember the pesky concealment doctrine, and remember Yudkowsky's words about why the rule exists in the first place. Read their internal arguments on these points and you will see, very nakedly, that the justification for their version of rule utilitarianism is a practical, instrumental one: not adopting it would make EAs look bad and reduce their prospects for success.
The rule against genocide, in their own telling, exists because genocide would reduce the long term likelihood of success for the effective altruist movement, and because telling the world "hey guys, we have rule utilitarianism now, no worries" lets you keep the same math running behind the scenes without losing social status, and therefore power and influence.
Think about what all of this means. With effective altruists at the helm of any institution with actual power and the ability to implement force, you are never more than a handful of effective altruists deciding that current circumstances, according to their wondrous utilitarian math, justify engineering a virus on purpose, or blowing up data centers on purpose, or assassinating people on purpose, and that it's worth the short term reputational cost to do so.
There is no actual rule against murder, genocide, or anything else.
There is no actual philosophical, ethical, or moral principle preventing any of this.
It's literally just a short term practical guardrail, held in place mostly for PR reasons. The second they think they can get away with it, the math says go.
## The worst of all: EAs are cowards
In my opinion, one of the worst and most embarrassing parts of all of this is that effective altruists, on top of everything else, are absolute cowards. They do not have the courage of their convictions.
Islamic jihadists are at least higher integrity than effective altruists, insofar as they will be honest with you about what their goals are. The jihadi will at the very least tell you what he is trying to achieve and why. With an EA, you can simply never know. (And yes, I am aware that "their doctrine permits deceiving outsiders" is the same argument bigots make about Muslims. The difference is that Singer wrote the paper.)
Effective altruists confronted with all of the above will squirm, they will feel the intuitive wrongness, and they will deflect, they will dissimulate, they will obfuscate, and they will deny the straightforward logic of it all, for the simple reason that they know they will be ostracized from polite society if they are honest, and rightfully so.
So instead, they hide it like cowards.
If you are going to believe something, own it. Have the courage of your convictions to actually stand by the simple, straightforward, logical implications of what you say you believe.
Of course, this is not true of all of them. Yesterday, September 18, an EA writer named Matthew Adelstein, who publishes as Bentham's Bulldog, put out an essay titled ["Insects Matter More Than People."](https://benthams.substack.com/p/insects-matter-more-than-people) His words, utterly beyond parody: "in total the welfare of insects matters more, in expectation, than the welfare of humans," and "there is some quantity of insects' interests that can outweigh a humans' interest." He stops there, and he doesn't write the next sentence which very obviously follows, so I will: by the same math there is some quantity of insects for which you should let the humans die.
A repugnant, morally reprehensible conclusion, but at least he said it in public. I do applaud the ones willing to bite the bullets that the logic of their beliefs implies.
But very few of them will. We are lucky, in some respect, that during the moment of maximum attention on effective altruism and its downsides, one of its influencers is willing to publish that headline. We should consider ourselves blessed by the Good Lord Himself that EAs have so little comprehension of social dynamics, culture, and politics. Thank the Lord they are not more socially adept.
Unfortunately, some of them are. The ones currently working inside the frontier research labs, and the ones gathering political influence in the United States across both parties, and in 2022 mostly in the Democratic Party, where SBF was [the second-largest CEO donor](https://www.cbsnews.com/news/ftx-sam-bankman-fried-political-donations-2022/) to Democratic causes behind only George Soros. Some of them are pretty sophisticated operators. So here you have the most extreme of extremist belief systems, with totalizing goals, a religious fervor, and a utopian or annihilatory eschatology, actively working in real time to accumulate as much power and influence as it can inside the most important institutions that exist today.
I would argue effective altruism poses a greater threat to the near term future of humanity than almost anything else.
EA is such a threat because EA is patently, nakedly evil.